We discuss using scipy’s optimization module optimize for nonlinear optimization problems,
and we will briefly explore using the convex optimization library cvxopt for linear optimization problems with linear constraints. This library also has powerful solvers for quadratic programming problems. For more information, see the project’s web site http://cvxopt.org
19.1 Importing modules
import numpy as npimport sympysympy.init_printing()from scipy import optimizeimport cvxoptimport matplotlib as mplimport matplotlib.pyplot as pltfrom IPython.display import displayimport scipyprint("scipy: ", scipy.__version__)print("cvxopt: ", cvxopt.__version__)
scipy:  1.16.0
cvxopt:  1.3.2
19.2 Classification of optimization problems
A general optimization problem considered here can be formulated as a minimization problem, \(\min_x f(x)\), subject to sets of \(m\) equality constraints \(g(x)=0\) and \(p\) inequality constraints \(h(x) \leq 0\)
Depending on the properties of the objective function \(f(x)\) and the equality and inequality constraints \(g(x)\) and \(h(x)\), this formulation includes a rich variety of problems
univariate(one dimensional) or multivariate(multidimensional)
linear programming problem or nonlinear programming problem
unconstrained, or constrained(equality and inequality constraints require different approaches)
convex or non-convex
continuous(smooth) or discontinuous
19.3 Univariate optimization
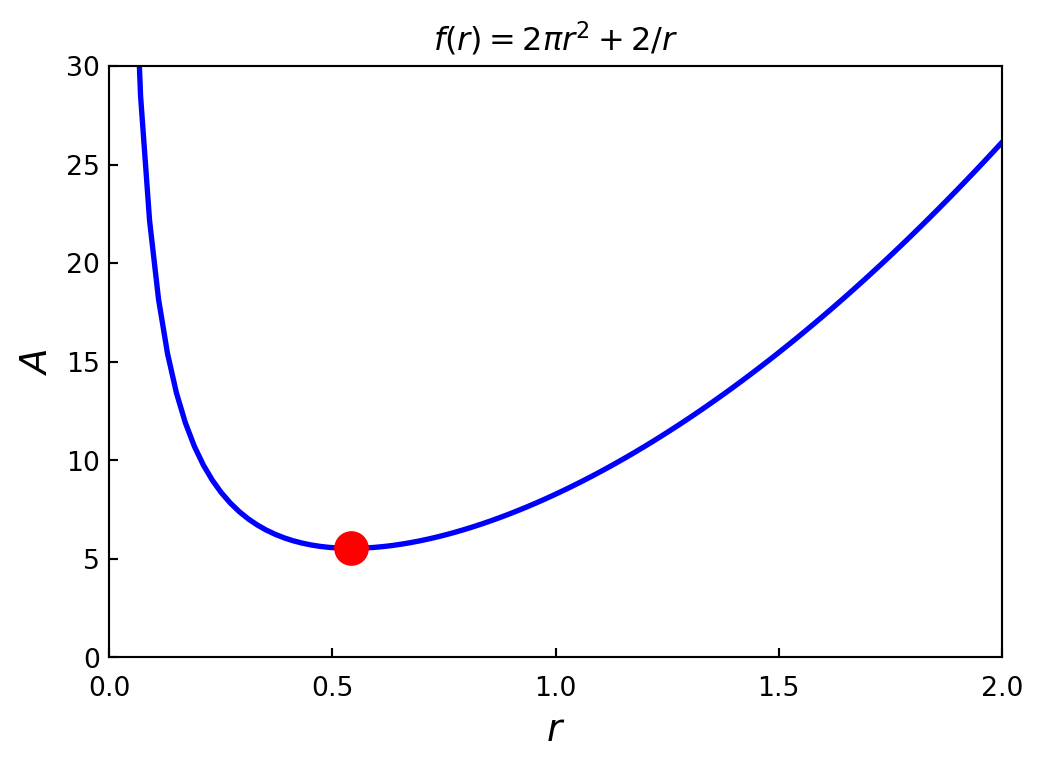
Minimize the area of a cylinder with unit volume. Here, suitable variables are the radius \(r\) and height \(h\) of the cylinder, and the objective function is
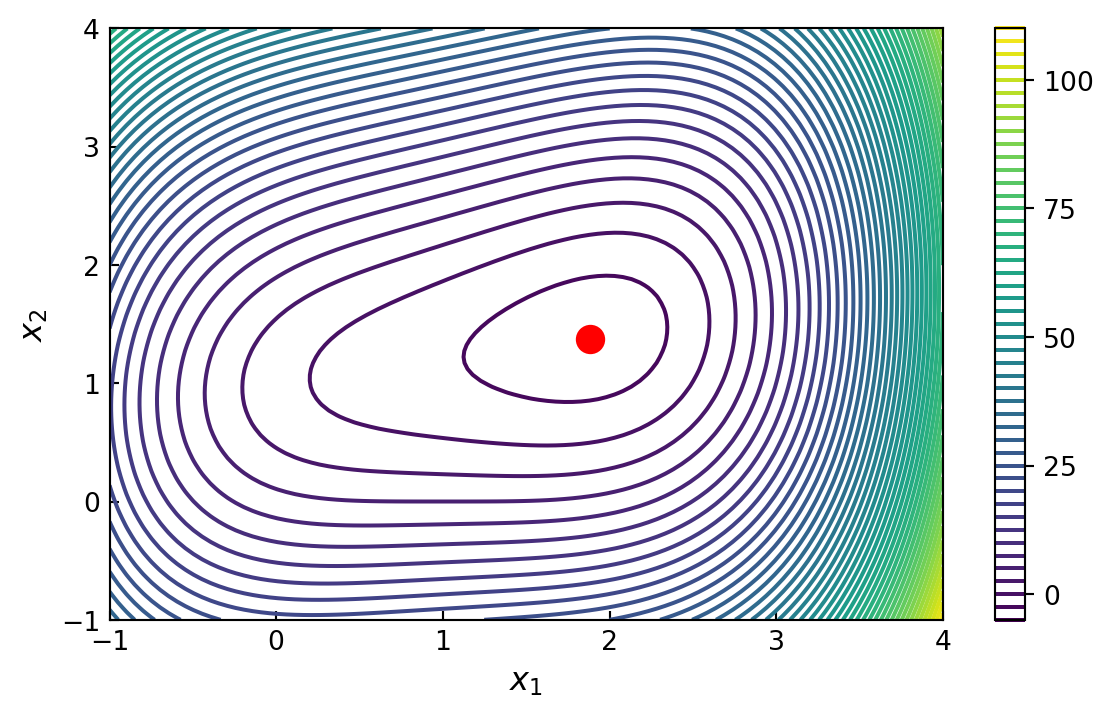
x1, x2 = sympy.symbols("x_1, x_2")f_sym = (x1 -1)**4+5*(x2 -1)**2-2*x1 *x2fprime_sym = [f_sym.diff(x_) for x_ in (x1, x2)]fhess_sym = [[f_sym.diff(x1_, x2_) for x1_ in (x1, x2)] for x2_ in (x1, x2)]
f = func_XY_X_Y(f_lmbda)fprime = func_XY_X_Y(fprime_lmbda)fhess = func_XY_X_Y(fhess_lmbda)
In scipy, the Newton conjugate gradient method is implemented in the function optimize.fmin_ncg (equivalently, optimize.minimize(..., method='Newton-CG')). This function takes the following arguments: a python function for the objective function, a starting point, a python function for evaluating the gradient, and (optionally) a python function for evaluating the Hessian
Methods that approximate the Hessian are known as quasi-Newton methods, and there are also alternative iterative methods that completely avoid using the Hessian
Two popular methods are the BFGS and the conjugate-gradient methods, which are implemented in scipy as the functions optimize.fmin_bfgs (the quasi-Newton method of Broyden, Fletcher, Goldfarb, and Shanno) and optimize.fmin_cg (the conjugate-gradient method of Polak and Ribiere)
Optimization terminated successfully.
         Current function value: -3.867223
         Iterations: 8
         Function evaluations: 18
         Gradient evaluations: 18
array([1.88292612, 1.37658523])
x_opt = optimize.fmin_bfgs(f, (0, 0))x_opt
Optimization terminated successfully.
         Current function value: -3.867223
         Iterations: 9
         Function evaluations: 39
         Gradient evaluations: 13
array([1.88292644, 1.37658595])
x_opt = optimize.fmin_cg(f, (0, 0))x_opt
Optimization terminated successfully.
         Current function value: -3.867223
         Iterations: 8
         Function evaluations: 54
         Gradient evaluations: 18
array([1.88292612, 1.37658522])
19.4.1 Brute force search for a global minimum
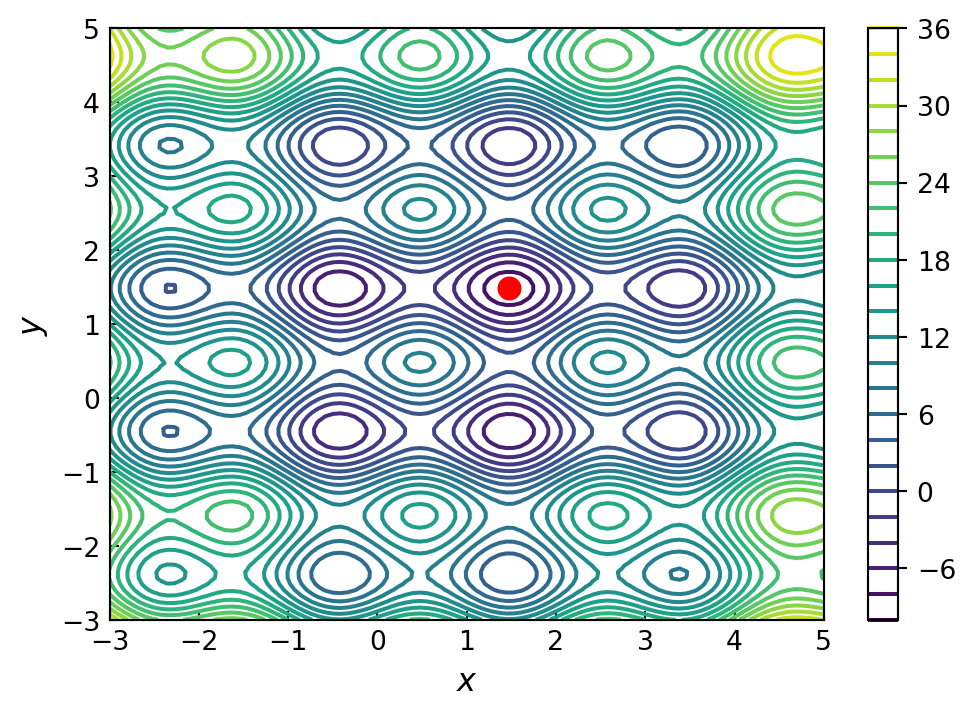
The methods for multivariate optimization that we have discussed so far all converge to a local minimum in general. For problems with many local minima, this can easily lead to a situation when the solver easily gets stuck in a local minimum, even if a global minimum exists
Although there is no complete and general solution to this problem, a practical approach that can partially alleviate this problem is to use a brute force search over a coordinate grid to find a suitable starting point for an iterative solver. At least this gives a systematic approach to find a global minimum within given coordinate ranges
In scipy, the function optimize.brute can carry out such a systematic search
To illustrate this method, consider the problem of minimizing the function
In general, a least square problem can be viewed as an optimization problem with the objective function \(g(\boldsymbol{\beta}) = \sum_{i=1}^m r_i^2(\boldsymbol{\beta})\), with the residuals \(r_i(\boldsymbol{\beta}) = y_i -f(x_i, \boldsymbol{\beta})\) for a set of \(m\) observations \((x_i, y_i)\). Here \(\boldsymbol{\beta}\) is a vector with unknown parameters that specifies the function \(f(x, \boldsymbol{\beta})\). If this problem is nonlinear in the parameters \(\boldsymbol{\beta}\), it is known as a nonlinear least square problem
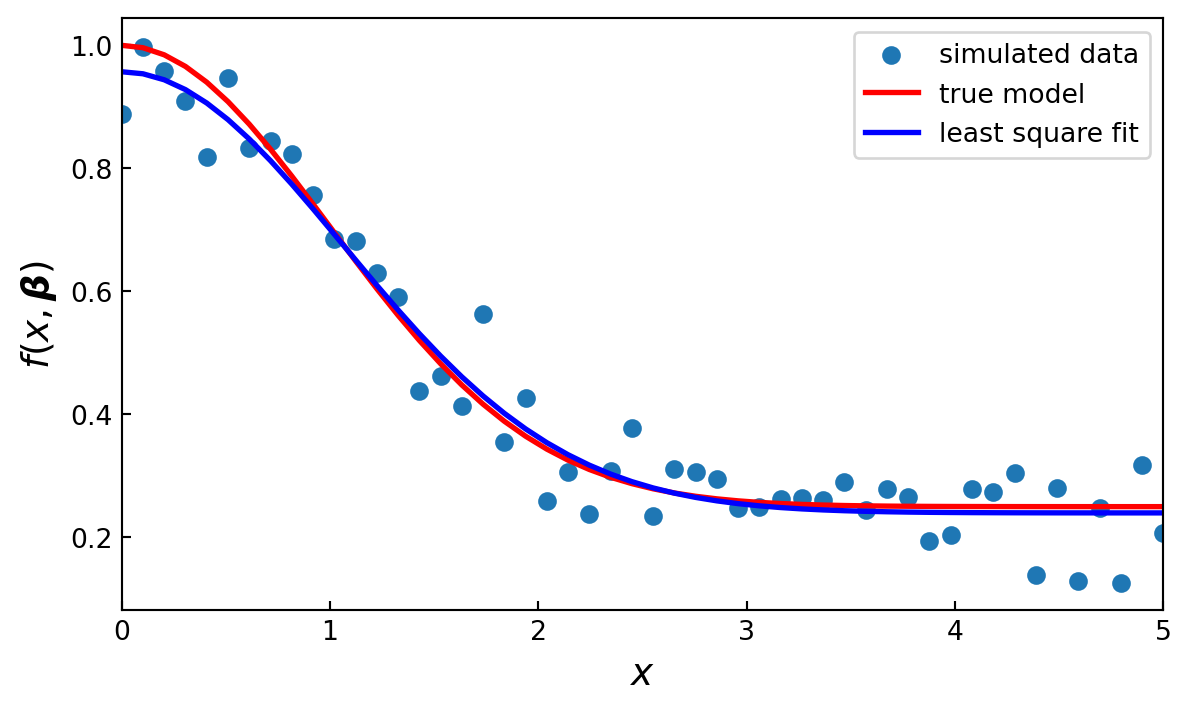
In scipy, the function optimize.leastsq provides a nonlinear least square solver that uses the Levenberg-Marquardt method. To illustrate how this function can be used, consider a nonlinear model on the form \(f(x,\boldsymbol{\beta})=\beta_1 +\beta_2 \exp \left( -\beta_3 x^2 \right)\) and a set of observations \((x_i, y_i)\)
The first step is to define a function for the residuals given the data and the model function, which is specified in terms of the yet-to-be determined model parameters
def g(beta):return ydata -f(xdata, *beta)
Next we define an initial guess for the parameter vector and let the optimize.leastsq function solve for the best least square fit for the parameter vector:
beta_opt, beta_cov = optimize.curve_fit(f, xdata, ydata)beta_opt # a convenience wrapper that also returns the covariance matrix
array([0.23979216, 0.7172281 , 0.44118037])
19.6 Constrained optimization
A simple form of constrained optimization is the optimization where the coordinate variables are subject to some bounds. These constraints are simple because they only restrict the range of the coordinate without dependencies on the other variables
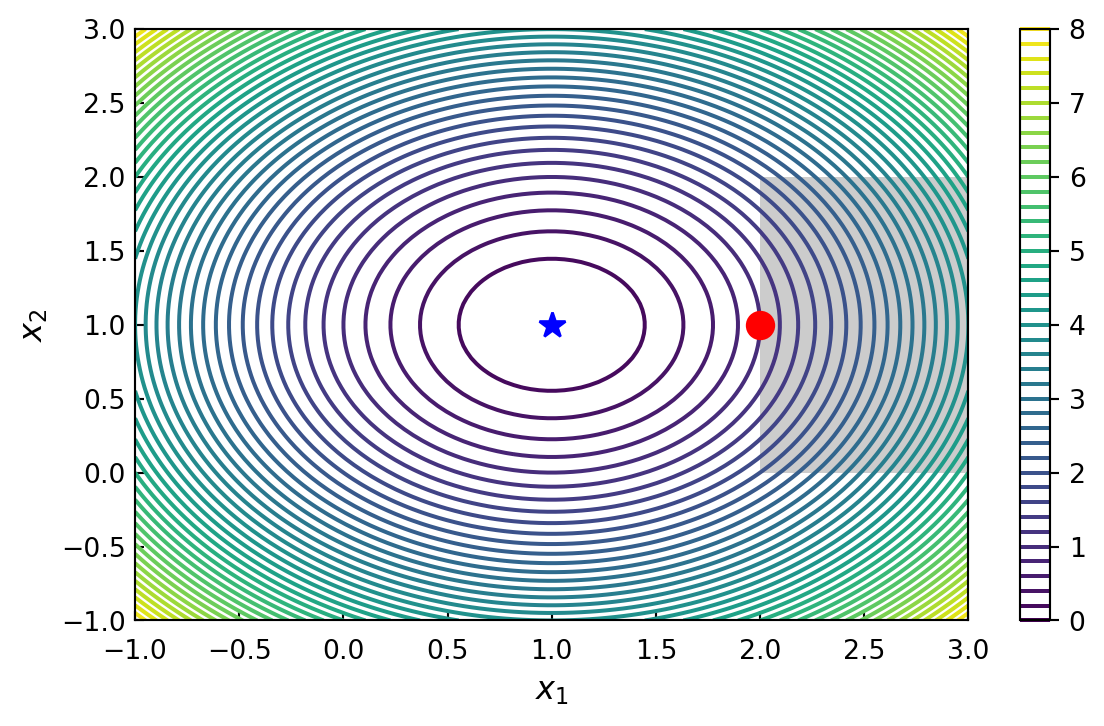
This type of problem can be solved using the L-BFGS-B method in scipy, which is a variant of the BFGS method. This solver is available through the function optimize.fmin_l_bfgs_b or via optimize.minimize with the method argument set to ‘L-BFGS-B’. To define the coordinate boundaries, the bounds keyword argument must be used, and its value should be a list of tuples that contain the minimum and maximum value of each constrained variable
Constraints that are defined by equalities or inequalities that include more than one variable are more complicated to deal with. However, using the Lagrange multipliers, it is possible to convert a constrained optimization problem to an unconstrained problem by introducing additional variables
For example, consider the optimization problem \(\min_x f(x)\) subject to the equality constraint \(g(x)=0\). In an unconstrained optimization problem the gradient of \(f(x)\) vanishes at the optimal points, \(\nabla f(x)=0\). It can be shown that the corresponding condition for constrained problems is that the negative gradient lies in the space supported by the constraint normal, \(-\nabla f(x) = \lambda J_g^T(x)\). Here \(J_g(x)\) is the Jacobian matrix of the constraint function \(g(x)\) and \(\lambda\) is the vector of Lagrange multipliers (new variables). This condition is the gradient of the function \(L(x,\lambda) = f(x) +\lambda^T g(x)\), which is known as the Lagrangian function. Therefore, if both \(f(x)\) and \(g(x)\) are continuous and smooth, a stationary point \((x_0, \lambda)\) of the \(L(x,\lambda)\) corresponds to an optimum of the original constrained optimization problem, \(x_0\)
Consider the problem of maximizing the volume \(f(x)=x_0x_1x_2\) of a rectangular box with sides of length \(x_0\), \(x_1\) and \(x_2\), subject to the constraint that the total surface area should be unity:
\[ g(x) = 2x_1 x_2 +2 x_0x_2 +2 x_1 x_0 -1 = 0 \]
To solve this optimization problem using Lagrange multipliers, we form the Lagrangian \(L(x, \lambda) = f(x) +\lambda g(x)\), and seek the stationary points where \(\nabla L(x, \lambda) = 0\)
x = x0, x1, x2, l = sympy.symbols("x_0, x_1, x_2, lambda")f = x0 *x1 *x2g =2*(x0 *x1 +x1 *x2 +x2 *x0) -1L = f +l *g
grad_L = [sympy.diff(L, x_) for x_ in x]sols = sympy.solve(grad_L)display(sols[0])display(sols[1])
There exist various numerical methods of applying this approach. One example is the method known as sequential least squares programming, abbreviated as SLSQP, which is available in the scipy as the optimize.fmin_slsqp function and via optimize.minimize with method='SLSQP'
The optimize.minimize function takes the keyword argument constraints, which should be a list of dictionaries that each specifies a constraint. The allowed keys (values) in this dictionary are type ('eq' or 'ineq'), fun (constraint function), jac (Jacobian of the constraint function)
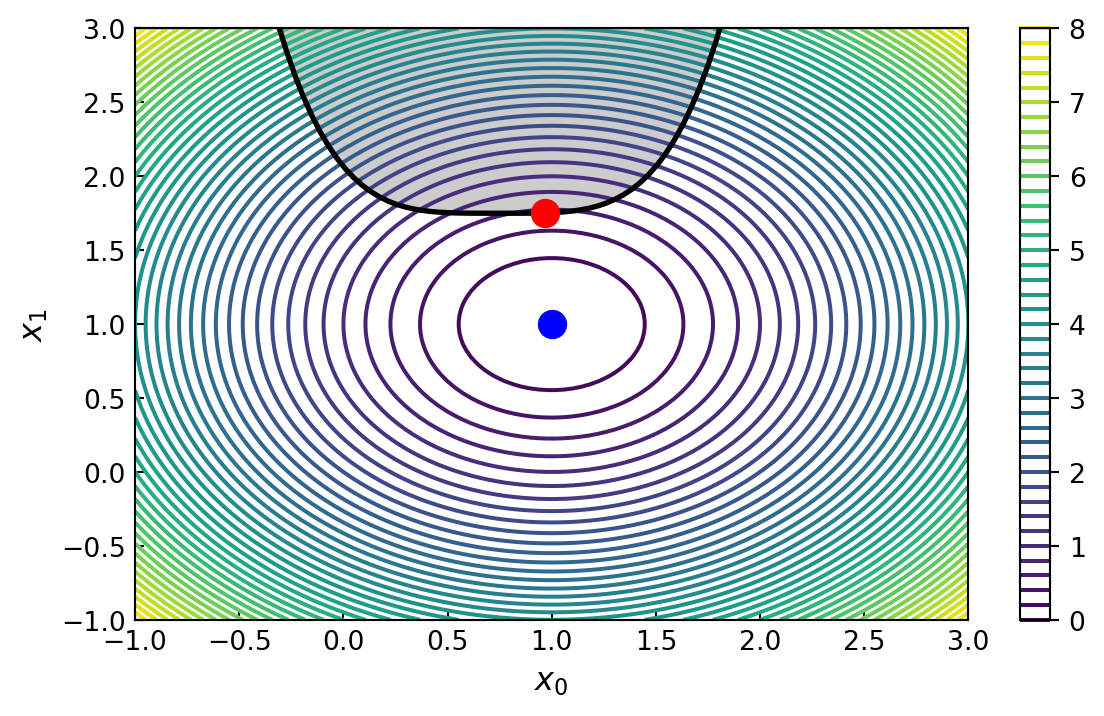
To solve problems with inequality constraints, all we need to do is to set type='ineq' in the constraint dictionary and provide the corresponding inequality function. To demonstrate minimization of a nonlinear objective function with a nonlinear inequality constraint, we return to the quadratic problem considered previously, but in this case with inequality constraint
For optimization problems with only inequality constraints, scipy provides an alternative solver using the constrained optimization by linear approximation (COBYLA) method. This solver is accessible either through optimize.fmin_cobyla or optimize.minimize with method='COBYLA'. The previous example could just as well have been solved with this solver, by replacing method='SLSQP' with method='COBYLA'
19.7 Linear programming
The solution to linear optimization problem must necessarily lie on a constraint boundary, so it is sufficient to search the vertices of the intersections of the linear constraint functions. This can be done efficiently in practice. A popular algorithm for this type of problems is known as simplex, which systematically moves from one vertex to another until the optimal vertex has been reached
There are also more recent interior point methods that efficiently solve linear programming problems. With these methods, linear programming problems with thousands of variables and constraints are readily solvable
Linear programming problems are typically written in the so-called standard form:
res = optimize.linprog(c, A_ub=A, b_ub=b) # bounds=(0, None) is the defaultres.x, res.fun
(array([1., 0., 3.]), -10.0)
The cvxopt library provides the linear programming solver cvxopt.solvers.lp(c, G, h), \(~\)which minimizes \(\mathbf{c}^T\mathbf{x}\) subject to \(\mathbf{Gx} \leq \mathbf{h}\) only. \(~\)Two points need care:
cvxopt.matrix fills its entries column by column, \(~\)so a nested list is read as a list of columns. \(~\)Converting a numpy array avoids this pitfall
The sign conditions \(\mathbf{x} \geq \mathbf{0}\) must be added as the extra rows \(-\mathbf{I}\,\mathbf{x} \leq \mathbf{0}\)
Both solvers reach the optimal value \(-10\), \(~\)but at different points. \(~\)Since \(f(\mathbf{x}) = -10\) on the whole edge between \((1, 0, 3)\) and \(\left(\frac{1}{4}, \frac{3}{4}, \frac{15}{4}\right)\) of the feasible region (where \(x_0+x_1=1\) and \(x_2 = 3+x_1\)), the optimum is not unique: \(~\)the simplex-type method of HiGHS returns a vertex, \(~\)while the interior-point method of cvxopt returns a point inside that edge
19.8 Quadratic programming
Quadratic programming problems are typically written in the so-called standard form: